Find us at booth #83, join us for a harbor side happy hour, or catch Gorish’s talk.

Sept, 16-18 > Learn more

Mamta Tainwala

July 29, 2026
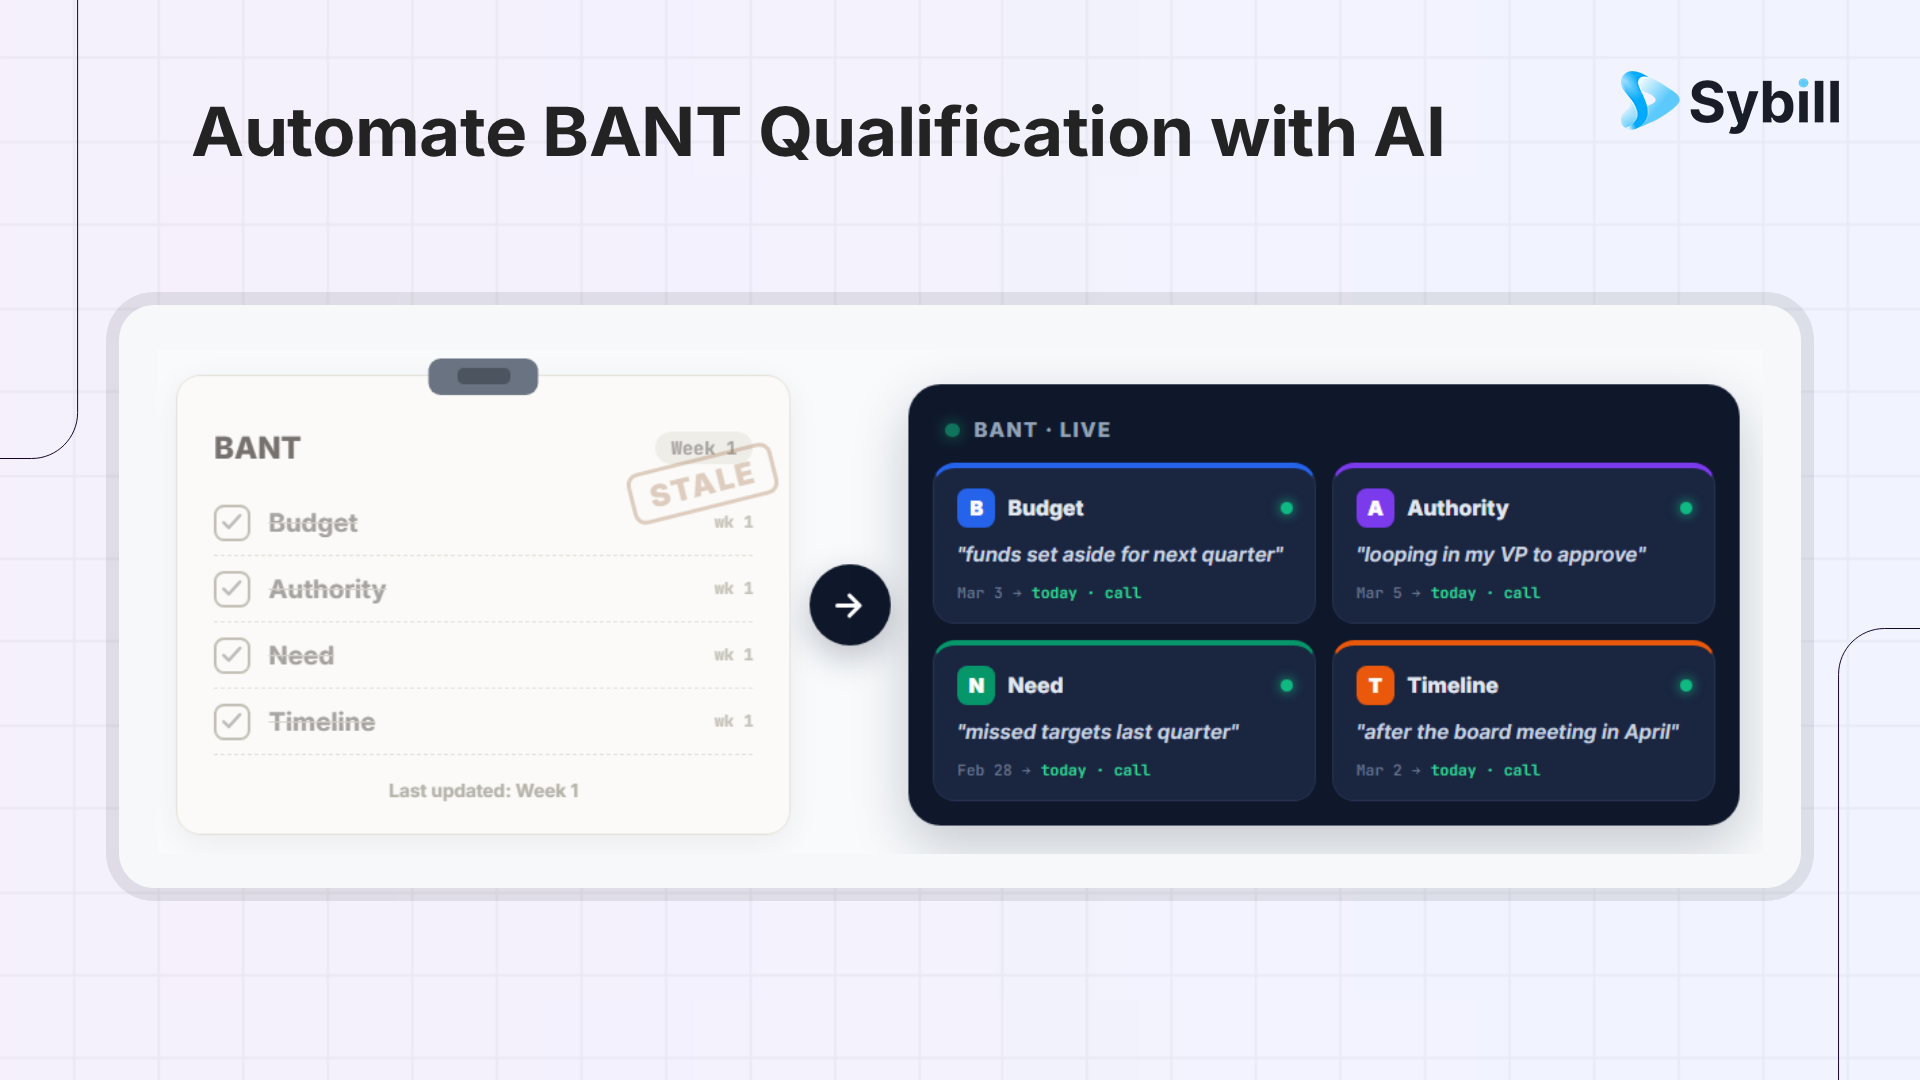
Automating BANT means AI extracts Budget, Authority, Need, and Timeline signals from every sales conversation and email, then updates the corresponding CRM fields continuously, turning a one-time qualification checklist into a live data layer. The rep never asks buyers to repeat themselves, never types the answers, and the deal record reflects qualification as it actually evolves across a multi-stakeholder cycle.
That is the promise. The rest of this post covers what BANT is (briefly), why manual BANT quietly fails in modern deals, what AI-driven qualification looks like signal by signal, and the three adoption traps that turn the whole project into shelfware.
BANT is a lead qualification framework developed at IBM that scores opportunities on four pillars: Budget (can they afford it), Authority (are you talking to the decision-maker), Need (do they genuinely need it), and Timeline (when will they buy). Its virtues are speed and simplicity, which is why it remains the default first framework for transactional and mid-velocity B2B motions decades later.
We will keep the fundamentals short, because they have their own home: our BANT qualification guide covers the framework's place in modern selling, the BANT vs MEDDIC comparison handles the enterprise question, and if you are framework-shopping generally, start with the lead qualification guide or consider GPCT for goal-first motions and SPICED for recurring-revenue depth.
This post is about a different problem: not whether BANT is the right framework, but why teams that chose it still end up with pipelines full of unqualified deals wearing qualified labels. That failure is almost never the framework. It is the execution model underneath it.
Manual BANT fails because it was designed as a snapshot and modern deals are a film. Qualification gets assessed once in early discovery, typed into the CRM (maybe), and never revisited, while the actual budget, stakeholders, and timeline shift across dozens of touchpoints. The record describes the deal as it looked in week one; the deal closes or dies based on what it became.
Walk through where the four letters actually decay:
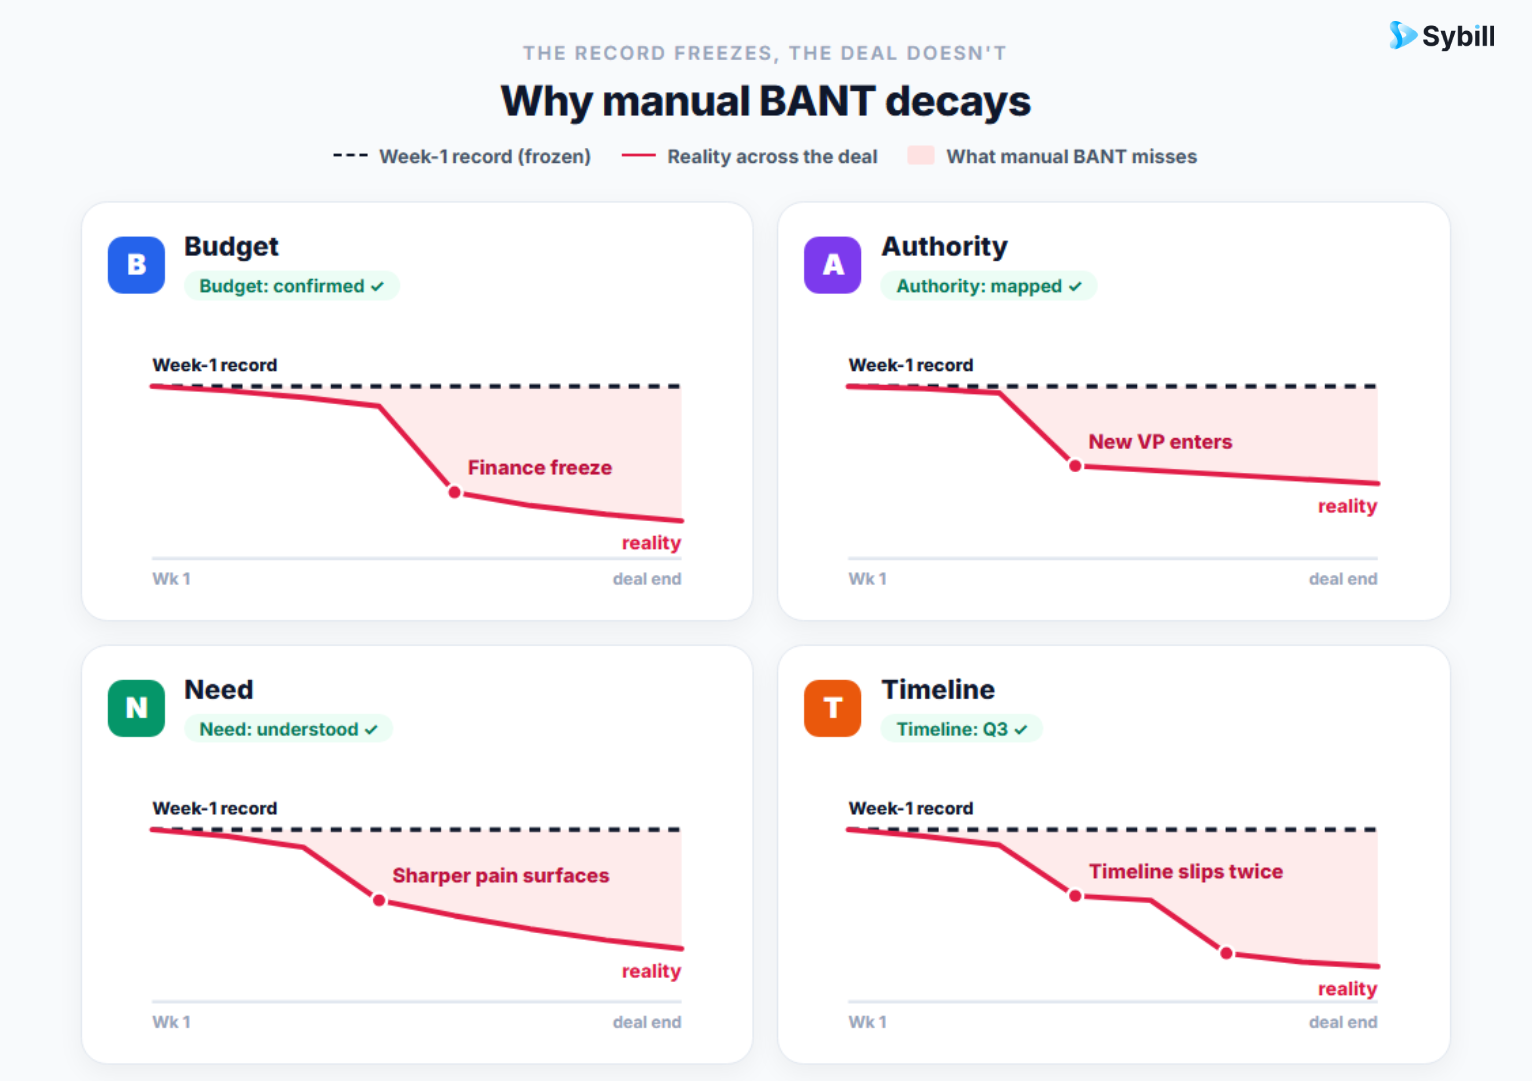
Budget gets confirmed in call one ("yes, we have budget") and then reorganized in month two when finance freezes discretionary spend. The CRM still says "Budget: confirmed." Nobody updates fields for bad news they half-heard in passing.
Authority was mapped to the enthusiastic director who took the first meeting. Three calls later, a VP and a procurement lead have entered the deal, and the real authority picture lives in the transcripts, not the record. Multi-stakeholder deals make week-one authority mapping obsolete almost by definition.
Need was captured as a summary sentence during discovery and never enriched, even as later calls surfaced the sharper, more fundable version of the pain. The best articulation of need in most deals happens mid-cycle, when trust is higher, and manual processes systematically miss it.
Timeline is the most perishable of all: "targeting this quarter" becomes "after the board meeting" becomes "once the new CFO settles in," and each revision was mentioned exactly once, verbally, while the rep was mid-conversation and rightly not taking dictation.
None of this is a rep discipline problem, and framing it as one is how teams end up nagging their way to fake compliance. It is a physics problem: a human cannot simultaneously run a consultative conversation and maintain a qualification database, and when forced to choose, the conversation correctly wins. The database loses, silently, on every call.
Which sets up the actual question of this post: what happens when the database maintains itself?
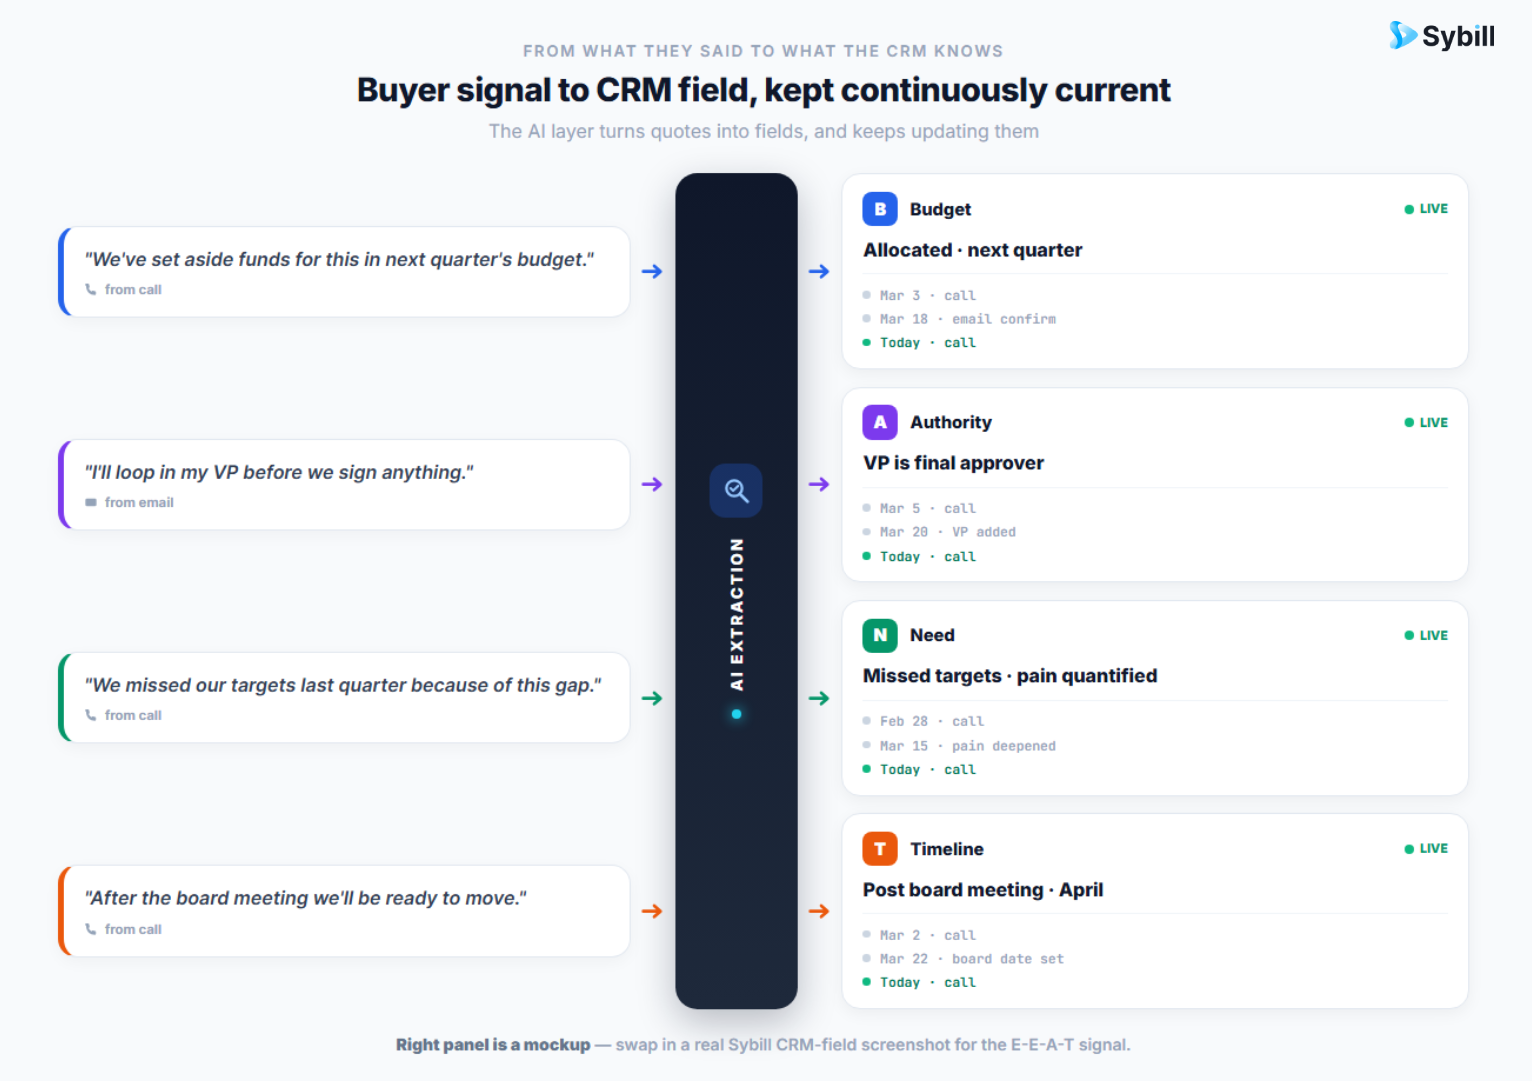
AI-automated BANT listens to every conversation and email, detects qualification signals in natural buyer language, and files them continuously: "we've allocated funds for this" updates Budget, "I'll need sign-off from procurement" flags Authority, frustration with current tools registers as Need, and "budget approval next quarter" sets Timeline. Every new touchpoint enriches the picture instead of replacing it.
The signal-detection layer is worth making concrete, because buyers almost never announce their BANT status in BANT vocabulary:
Budget signals hide in phrases like "we've already set aside spend for a tool like this," "that's above what we planned," or a question about annual versus monthly billing. Each one moves the Budget picture, and each one is exactly the kind of passing remark a note-taking rep loses.
Authority signals sound like "let me loop in my VP," "procurement will want to see this," or the quiet tell of a new title appearing on the invite list. Mapped over time, these build the real decision graph of the account.
Need signals range from explicit ("we missed our targets because of this") to structural (the same pain described by three different stakeholders in three different calls, which is a far stronger qualification than one champion's enthusiasm).
Timeline signals attach to events: board meetings, contract expiries, fiscal-year boundaries. The AI's job is catching the date and, just as importantly, catching the revision two calls later.
Then the workflow layer puts the signals where work happens. Magic summaries surface the qualification-relevant moments after each call; CRM Autofill writes standard and custom BANT fields without a rep touching a keyboard, the same conversation-tier automation logic that separates real CRM automation from activity capture; Ask Sybill answers point questions across the deal history ("what did they actually say about budget?"); and deal inspection rolls it up to the pipeline level, flagging deals whose BANT picture has gaps or has gone stale. From there, personalized follow-ups and AI tasks act on what was detected: the email reinforcing urgency around the timeline the buyer named, the task to multithread past the authority gap.
The compounding effect is the point most demos undersell: interaction one produces a sketch, interaction seven produces a dossier. Sybill has analyzed over 33 Million sales conversations, and the qualification picture that emerges from a full conversation history is consistently different from, and more predictive than, the one captured in week one. Deals qualified on the film close differently than deals qualified on the snapshot.
Your buyers already answered the BANT questions. On calls. Out loud. Sybill catches every signal and keeps the fields current, so qualification reflects the deal as it is, not as it was. Get started for free with Sybill.
Three traps sink most BANT automation projects: deploying AI without aligning it to your actual sales motion (it captures noise instead of insight), buying transcription dressed as understanding (a searchable pile of notes is not qualification), and never grounding the system in your real deals (generic signal detection misses how your buyers actually talk). All three are avoidable, and all three are avoidable before you buy.
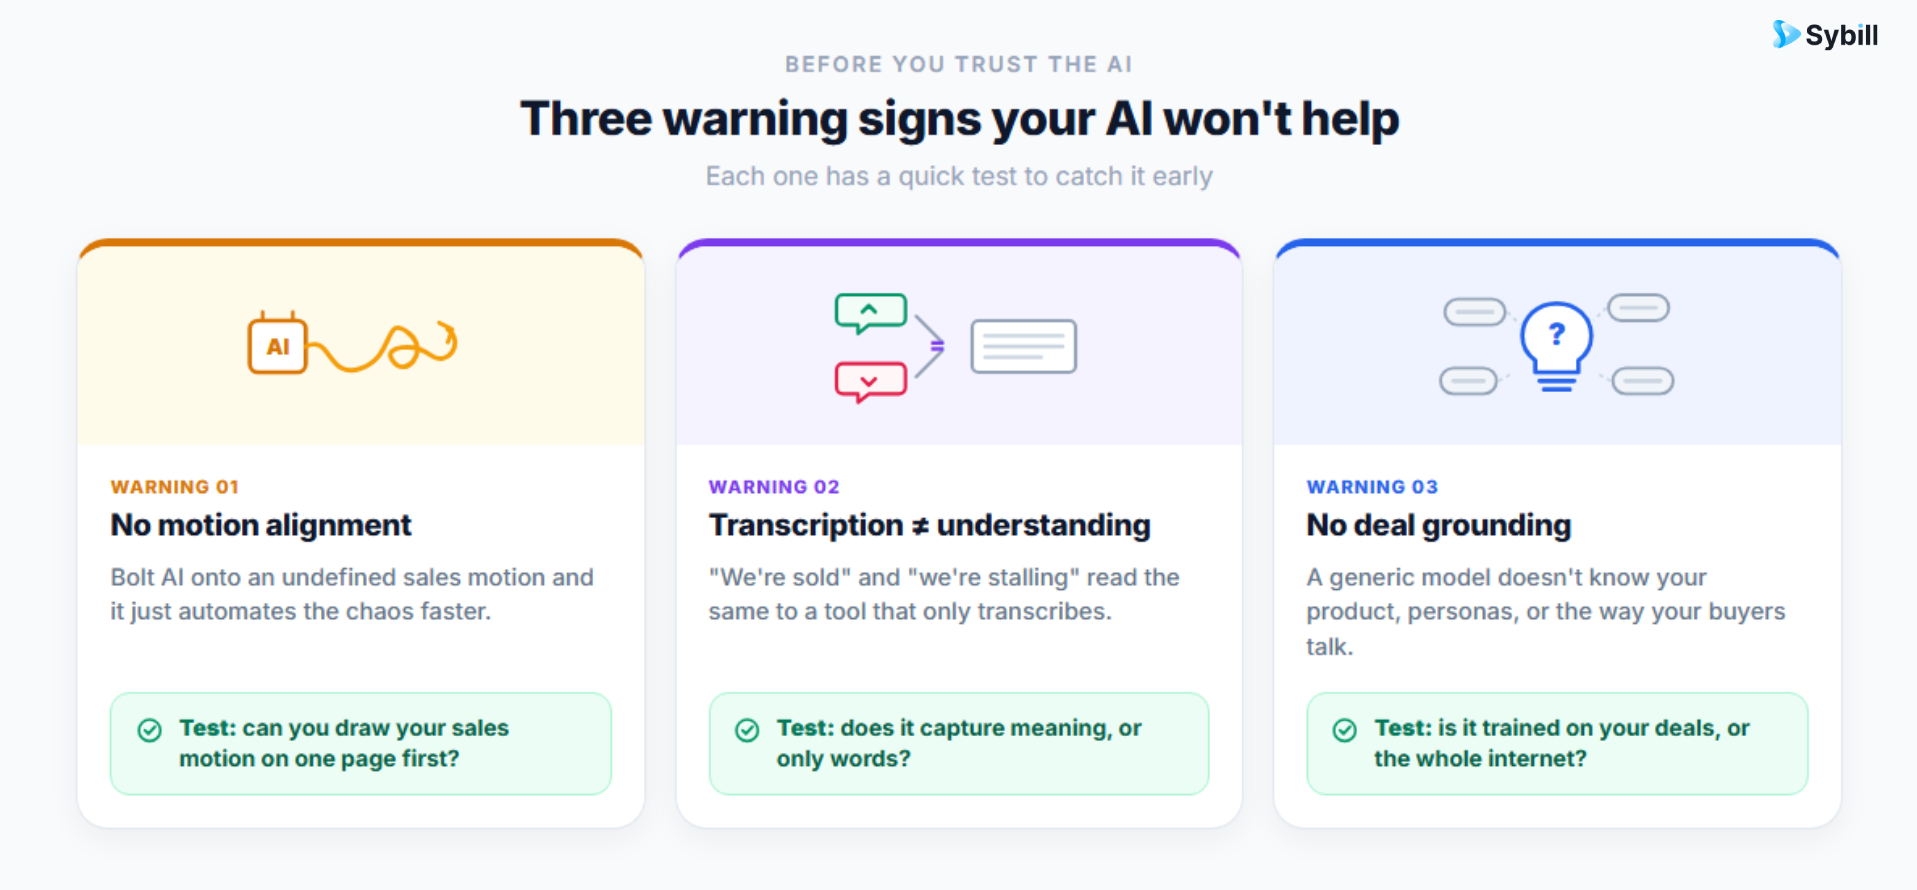
Trap 1: No sales motion alignment. Every org runs qualification differently: some gate on budget upfront, others establish need first; some close in one call, others run 90-day multi-stakeholder cycles. AI dropped into an undefined motion faithfully automates the confusion. The fix is boring and non-optional: define what "qualified" means at each stage, agree on it internally, and make sure CRM fields and pipeline stages reflect the real workflow before the tool arrives. Automation amplifies whatever process exists, including the absence of one.
Trap 2: Recording without understanding. A tool that transcribes "we're not planning to buy this quarter" and "we'd love to move forward but need budget approval first" has captured both sentences and understood neither, because they are opposite qualification signals wearing similar words. If the output is transcripts and generic summaries, you have not automated BANT; you have built a second inbox. Test candidates on real calls across personas and stages, and demand contextual mapping to the four pillars, not just accurate speech-to-text.
Trap 3: No grounding in your deals. Your buyers have their own vocabulary for budget pressure, their own procurement rituals, their own tells. A system tuned on generic sales calls will miss them. Run the early weeks against real won and lost deals, audit the outputs against what your best reps know to be true, and refine field prompts accordingly. This doubles as the trust-building exercise that decides adoption: reps who watch the system be right about their own deals stop treating it as surveillance and start treating it as staff. Clean grounding also depends on clean substrate, which is where CRM data hygiene stops being a chore and starts being a prerequisite.
The common thread: none of the traps is a technology failure. They are all versions of automating before defining, which is the oldest failure in sales operations wearing a new acronym.
Yes, with one amendment: BANT the framework remains a fast, teachable qualification structure, but BANT the one-time checklist is obsolete in multi-stakeholder deals. The relevant version in 2026 is continuous BANT: the same four pillars, assessed automatically across the whole deal lifecycle rather than once in discovery. The framework did not age out; the execution model did.
This reframe also answers the perennial "BANT is dead" discourse honestly. The critics are right that a rep mechanically firing four questions at a modern buyer ("Do you have budget? Who decides? What's your pain? When are you buying?") deserves the eye-roll it gets, and they are right that buyers now arrive researched, multi-threaded, and allergic to interrogation. But the conclusion does not follow. The problem was never that budget, authority, need, and timeline stopped mattering; no deal in history has closed without all four resolving. The problem was extracting them through a questionnaire instead of through listening.
Continuous, AI-maintained BANT resolves exactly that: the buyer talks naturally, the rep sells naturally, and the four pillars assemble themselves from what was actually said. The framework survives by finally being executable the way it was always meant to work: as understanding, not as interrogation. Good discovery was always the delivery mechanism; the checklist was only ever a crutch for what didn't get captured.
Every qualification framework ever written shares one silent assumption: that someone will keep the answers current. For forty years, that someone was a rep with a notepad and seven other jobs, which is why every pipeline in history has carried deals whose qualification data described a version of the account that no longer existed.
That assumption is now optional. The four questions IBM wrote down still decide every deal. The difference is that answering them, tracking them, and re-answering them as the deal evolves is no longer a human chore; it is an ambient property of having the conversations at all.
Your reps ask nothing they were not going to ask. Your buyers repeat nothing. And your CRM, for the first time, knows what your deals actually look like today.
Get started for free with Sybill or book a demo and put your qualification on film.
Budget, Authority, Need, and Timeline: the four pillars IBM's framework uses to qualify opportunities. Budget asks whether the prospect can afford the solution, Authority whether you are engaging the decision-maker, Need whether a genuine problem exists, and Timeline when a purchase would realistically happen.
BANT is a lightweight four-factor qualification check suited to transactional and mid-velocity deals. MEDDIC (and MEDDPICC) goes deeper into enterprise buying mechanics: metrics, economic buyer, decision criteria and process, paper process, and champions. Choose by deal complexity: BANT for speed, MEDDIC for long procurement-heavy cycles.
Open questions beat interrogation: "How have purchases like this been funded before?" (Budget), "Who else will weigh in on this decision?" (Authority), "What happens if this problem goes unsolved for six months?" (Need), and "Is there a date this needs to be working by?" (Timeline). With AI-assisted qualification, most answers surface in natural conversation and are captured automatically.
The framework is not; the one-time-checklist execution is. Budget, authority, need, and timeline still decide every B2B deal, but in multi-stakeholder cycles they shift constantly, so qualification must be continuous. Modern teams keep BANT and replace the manual snapshot with AI that updates the picture across every touchpoint.
AI can detect and maintain qualification signals (budget cues, stakeholder changes, need articulation, timeline events) from conversations and emails, and keep CRM fields current without rep effort. The judgment calls (whether to pursue, how to multithread, when to walk) remain human; AI's job is ensuring those calls run on complete, current evidence.
Budget, Authority, Need, and Timeline: the four pillars IBM's framework uses to qualify opportunities. Budget asks whether the prospect can afford the solution, Authority whether you are engaging the decision-maker, Need whether a genuine problem exists, and Timeline when a purchase would realistically happen.
BANT is a lightweight four-factor qualification check suited to transactional and mid-velocity deals. MEDDIC (and MEDDPICC) goes deeper into enterprise buying mechanics: metrics, economic buyer, decision criteria and process, paper process, and champions. Choose by deal complexity: BANT for speed, MEDDIC for long procurement-heavy cycles.
Open questions beat interrogation: "How have purchases like this been funded before?" (Budget), "Who else will weigh in on this decision?" (Authority), "What happens if this problem goes unsolved for six months?" (Need), and "Is there a date this needs to be working by?" (Timeline). With AI-assisted qualification, most answers surface in natural conversation and are captured automatically.