Find us at booth #83, join us for a harbor side happy hour, or catch Gorish’s talk.

Sept, 16-18 > Learn more

Mamta Tainwala

September 13, 2026
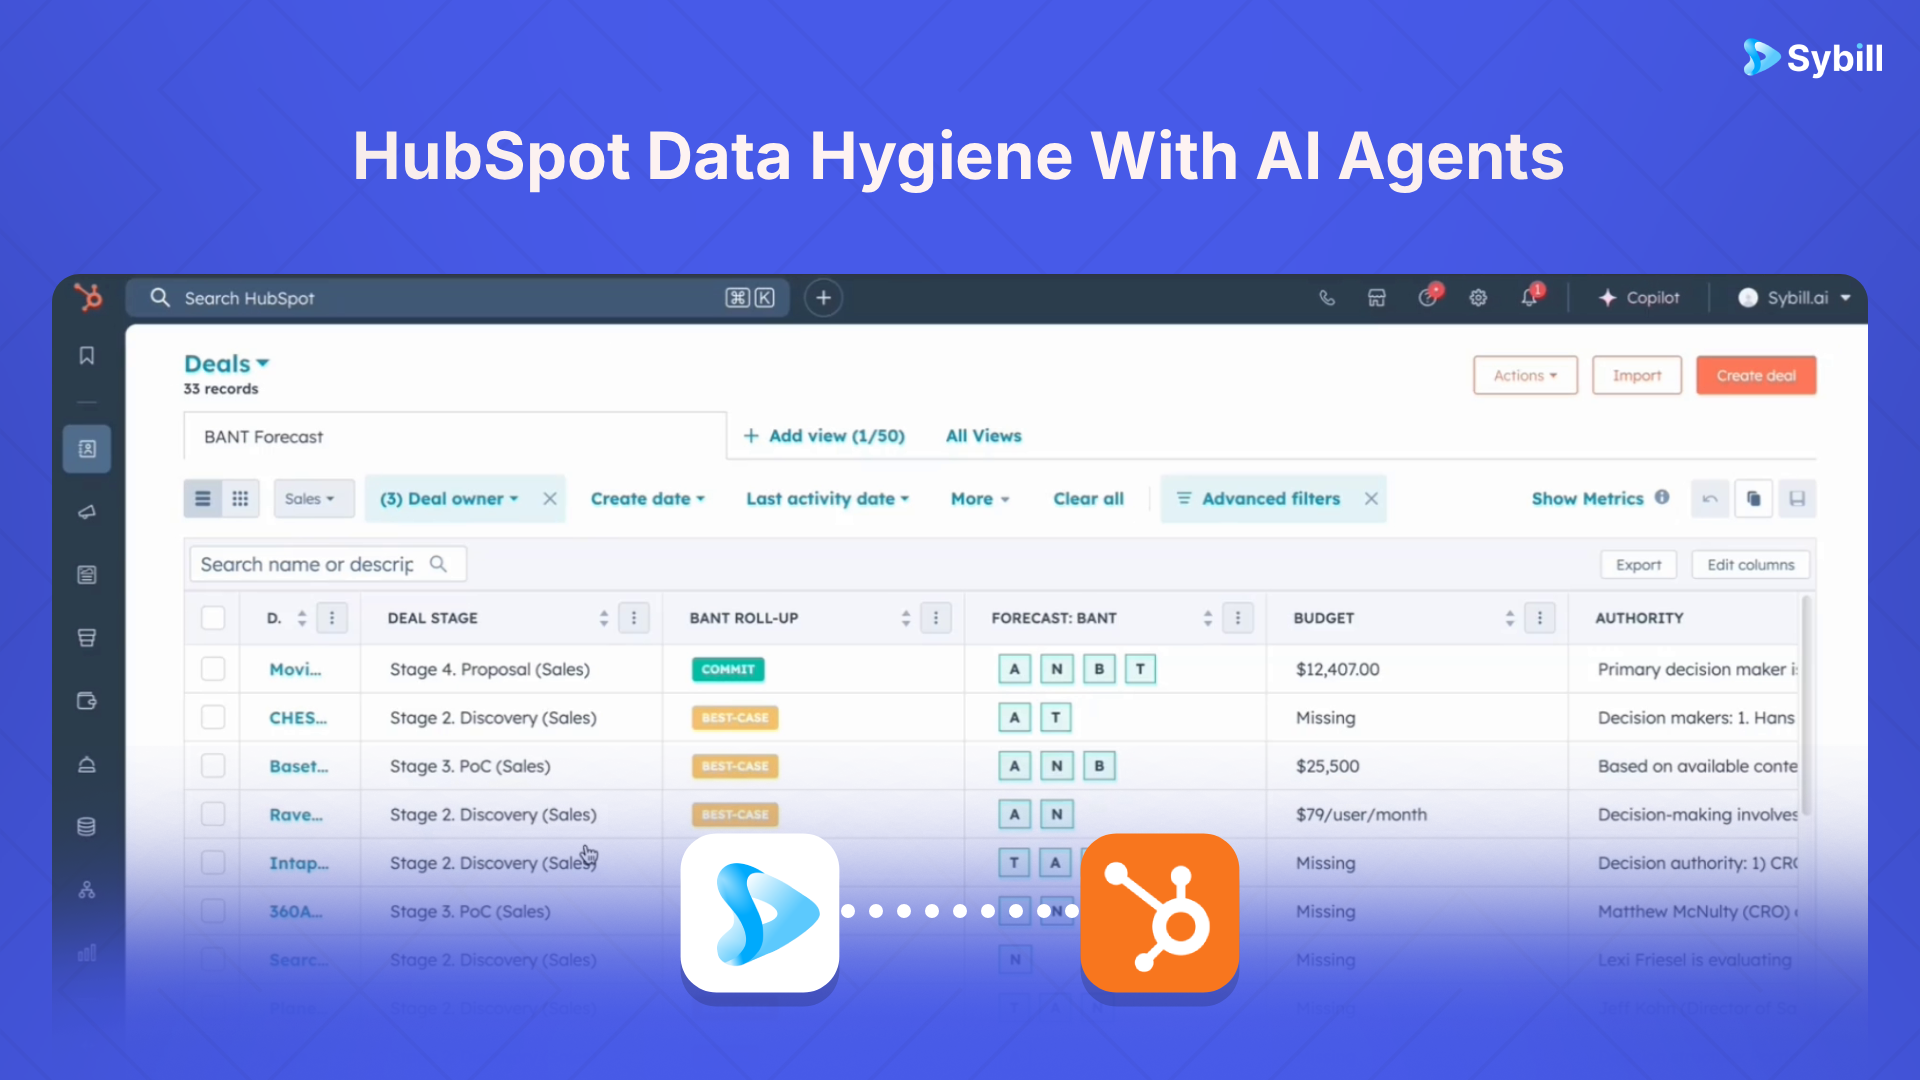
TL;DR: HubSpot data goes bad at the moment of entry, not in the months after. Reps log from memory, under time pressure, in free text, and every downstream workflow, report, and forecast inherits that. HubSpot's native data quality tools are good at fixing duplicates and formatting on contacts and companies, and they do almost nothing for the deal-level qualification properties your forecast reads. AI agents close that gap by capturing the call, extracting structured values, validating them against your property schema, and writing them into HubSpot when the call ends. Cleanup sprints treat the symptom. Agents fix the input.
Open ten late-stage deals in your HubSpot portal right now. Count how many have an Economic Buyer populated, a Decision Date that is a real date, and a Next Step that is more specific than "follow up."
If the answer is fewer than seven, you do not have a rep discipline problem. You have an architecture that asks a human to reconstruct a 45-minute conversation from memory, in structured fields, in the four minutes before their next call. It produces exactly the data it was designed to produce: late, partial, and phrased twenty different ways by twenty people.
This post covers how HubSpot data decays, what HubSpot's own hygiene tools do and do not cover, and what changes when an AI agent owns the input layer.
HubSpot data decays because manual entry happens after the call, from memory, under time pressure, and in inconsistent language. Those four conditions produce three failure patterns: delay (fields updated days later or never), omission (context the rep did not think to log), and taxonomy drift (the same fact recorded five different ways).
Each one has a specific HubSpot consequence.
Delay breaks your workflows. A HubSpot workflow fires when a property meets a condition. If "Discovery Complete" gets ticked Thursday for Monday's call, the follow-up task fires three days late and the deal sat in the wrong stage through Tuesday's pipeline review. If it never gets ticked, nothing fires and nothing tells you. More in our 15 HubSpot workflow examples.
Omission breaks your handoffs and risk detection. Competitor mentions, procurement blockers, the VP of Legal who "still needs to sign off": none are line items on a rep's mental checklist, so they land in a free-text note at best. HubSpot cannot route, alert, or report on a paragraph. The CSM who inherits that deal runs discovery with a customer who already had it.
Taxonomy drift breaks your reporting. One rep types "budget confirmed." Another writes "they have $$." A third picks the wrong enumeration value because none of the options matched exactly. Filter your pipeline on "Budget Confirmed = True" and you get a fraction of the deals where budget was actually confirmed, and you have no way of knowing which fraction.
The cleanup sprint is the standard response, and it holds for about a quarter. Then Monday comes, the same reps take the same calls under the same time pressure, and the same three patterns refill the portal. You cannot out-clean a broken input. Our CRM data hygiene guide covers the general principle; this post is HubSpot specifically.
HubSpot's data quality tools, found under Reports, Data Management, Data Quality, monitor and fix duplicates, formatting issues, enrichment coverage, and property usage across contact and company records. They are genuinely useful for the problems they target. They do not address deal-level qualification data, which is where the forecast-relevant gaps live.
Credit where it is due, and it is due: HubSpot has built real tooling here.
Now read that list again and notice the scope. Duplicates, formatting, and property insights operate on contacts and companies. The deal object, where your Economic Buyer, Identified Pain, Decision Criteria, and Competitor fields live, is covered by exactly one mechanism: conditional stage properties, which is a gate, not a fill.
And a gate has a known failure mode. Require six fields before a deal can enter Proposal, and a rep with a call in four minutes will supply six values. Some will be "n/a." Some will be guesses. The popup is satisfied, the field is populated, and the field is wrong, which is worse than blank because blank at least tells the truth. Anyone who has tried to get a sales team to update the CRM through enforcement alone knows how this ends.
HubSpot's Breeze AI narrows the gap further by suggesting record updates after a recorded call. Useful, and still a suggestion: a human reviews and accepts each one, which puts the bottleneck back in the exact spot that was failing.

An AI agent improves HubSpot data hygiene by treating the conversation, not the rep's memory, as the source of record. It captures the call, extracts structured values (stakeholders, budget, timeline, pain, competitors, next steps), maps each to a defined HubSpot property, validates the value against that property's type and options, and writes it when the call ends.
That sentence contains six steps, and each one matters for HubSpot specifically.
1. Capture at the source. The agent joins or records the call, so the input exists before human memory has compressed it. What the buyer actually said about budget is the input, not what the rep recalled about it at 5:47 pm.
2. Extract entities, not summaries. A summary is prose. An extraction is a set of discrete facts: "VP of Legal, Marcus, approval gate" is three values (a contact, a role, a decision-process step), not one sentence. This is the difference between a note HubSpot stores and a property HubSpot can act on. If you want the anatomy of how agents do this, our explainer on AI agent components breaks it down.
3. Map to your schema, not a generic one. Your HubSpot portal has properties with specific internal names, types, and option lists. "Decision Date" is a date picker. "Budget Confirmed" is a checkbox. "Primary Competitor" is an enumeration with seven allowed values. The agent's job is to write to those, by internal value, so integrations and workflows keep resolving. A tool that dumps a summary into a notes field has not done this step.
4. Validate against the property type. "Before Q4" is not a valid date. The agent has to resolve it to one (end of Q3, or a specific date if the buyer named it) or flag it for review. A budget of "about 50" has to become a number with a unit. A competitor mention that is not in your enumeration list has to route somewhere a human can see it, rather than silently failing or being crammed into the wrong option. This is the step that separates hygiene from a faster way to create mess.
5. Write on completion, without a queue. The field is populated when the call ends. Not when the rep reviews a suggestion, not when Thursday's admin block happens. This is what makes the downstream workflow fire on Monday instead of Thursday.
6. Flag what did not map. Every real conversation contains something your schema did not anticipate. A good agent surfaces it (unmapped stakeholder, new competitor, a constraint with no property) rather than dropping it. That flag is also how RevOps learns which properties to add.
To be clear: this is extraction, matching, and validation against rules you configure, not magic, and the setup step is real. And an agent writing to your CRM needs the same governance as any integration with write access: scoped permissions, an audit trail, a named owner. Our guide to AI agent security and permissions covers what to require first.
AI agents can populate deal properties across the full lifecycle: buyer committee (economic buyer, champion, decision process), qualification (budget, decision date, procurement, competitors), discovery (pain, compelling event, current stack), conversation signals (objections raised, sentiment, next step), and post-sale handoff context (success criteria, risks, onboarding owner).
The practical set depends on your schema and methodology, but the shape looks like this:
Methodology fields sit on top of this. If you run MEDDPICC, the agent scores each element against the transcript and writes completion to the corresponding properties, so a deal cannot show 80% probability while Metrics and Economic Buyer sit empty. Our walkthrough of auto-updating MEDDPICC and BANT fields in HubSpot from call notes covers the property-by-property mapping, and MEDDIC as a sales process covers what each element actually requires.
Stakeholders are where manual entry fails hardest. "Priya owns the budget but Rob in IT has to sign off on security" is two contacts, two roles, and one dependency. A rep writing notes at speed captures maybe one. An agent associates both contacts with the deal and writes their roles, which is the raw material for buyer intelligence across the account, and the reason the CSM later knows who Rob is.
Agent-written data is more accurate because it is extracted from what was said rather than reconstructed from what was remembered, it applies one taxonomy across every rep, and it captures the context reps consistently omit. The agent has no quota, no optimism, and no 5:00 call.
Three mechanisms, all mundane, all decisive:
Objectivity. Sales optimism is not a character flaw, it is a job requirement, and it leaks into CRM entry in predictable ways. Budgets round up. Objections get logged as "addressed" when they were acknowledged. Stages advance on hope. An agent records that the buyer said "we'd need to see the security review before committing" as an open dependency, because that is what was said.
Uniform taxonomy. Every rep's calls run through the same extraction against the same enumeration list. "Budget Confirmed" means one thing across the whole portal, which is the only condition under which a pipeline filter on that property returns a trustworthy result. This is what makes segment-level reporting and AI-driven deal reviews possible without a data cleanup project first.
Completeness. The agent processes the full transcript. It does not decide in the moment what is worth logging. So the offhand competitor mention in minute 38, the procurement timeline buried in small talk, and the second stakeholder's name all land in properties instead of evaporating.
Sybill is an AI sales agent that captures every customer call and writes structured values to your HubSpot deal properties automatically when the call ends, mapped to your schema, with no rep review queue. It then does the work the call created: follow-up drafts, tasks, and risk flags built from the conversation itself.
Disclosure: this is our product. Everything above applies to the category. Here is what it looks like in HubSpot specifically, drawing on around 33 million sales calls analyzed:
The division of labor with HubSpot is clean. HubSpot's data quality tools own duplicates, formatting, and property governance on contacts and companies. HubSpot workflows own what happens when a field changes. Sybill makes sure the deal fields change, with real values, when the conversation happens. Setup runs through the HubSpot integration, and the help center has the configuration steps. For where this fits among other AI agents for sales teams, that guide covers the wider landscape.
Get started for free with Sybill
Roll out AI-driven hygiene in four steps: map your deal properties and define what each value means, pilot with two or three reps against real calls for 30 days, reposition HubSpot's native rules as validation rather than enforcement, and run a monthly fill-rate audit on the properties your forecast reads.
Step 1: Map the schema first. For each deal property your pipeline review or forecast depends on, write down the type, the allowed values, and a one-line definition of "populated correctly." Archive the properties HubSpot's property insights show as unused while you are there. This exercise usually reveals that "Budget Confirmed" has meant three different things to three different managers.
Step 2: Pilot on real calls, with your best reps. Run the agent for a small group for 30 days. Check agent-written properties against the transcript on a sample of calls, not against what the rep would have typed, since the rep would have typed nothing. Your top performer will find the mapping errors faster than a team-wide rollout will.
Step 3: Let HubSpot's native rules validate instead of enforce. Once fields arrive pre-populated, conditional stage properties stop being a popup reps route around and start being a check that confirms populated values are the right type. Duplicate management and formatting fixes keep doing their job on contacts and companies. The agent and the native tools work on different objects and complement each other.
Step 4: Audit fill rates monthly. Pick the five to eight properties your forecast reads. Each month, pull deals in your last two open stages and check what percentage have those properties populated with real values. That number is your hygiene score, and it is the honest measure of whether the automation is working. If it drifts, the cause is almost always a schema change nobody told the agent about.
On governance: RevOps owns the schema, so when you rename a property or add an enumeration value, the agent's mapping follows. The vendor owns extraction quality and the API connection. Name both owners before go-live; "who owns it when it breaks" decides whether this becomes infrastructure or another abandoned integration. If all of this is your Tuesday, that is the job Sybill exists to shrink.
HubSpot data hygiene is the ongoing practice of keeping records complete, accurate, consistently formatted, and free of duplicates so that workflows, reports, and forecasts built on them are trustworthy. It covers contacts, companies, and deals, though most native tooling focuses on the first two.
HubSpot's data quality tools cover duplicate management for contacts and companies, formatting issue detection with automatic fixes on Data Hub Professional and Enterprise, enrichment coverage, and property insights showing empty or unused properties. Conditional stage properties add required fields at deal stage transitions. None of these fill deal qualification data from calls.
AI agents capture the sales call, extract structured values such as stakeholders, budget, timeline, and competitors, map each to a specific HubSpot property by internal value, validate the value against the property's type and options, and write it through HubSpot's API when the call ends. Unmapped values are flagged for review rather than dropped.
Duplicate contacts and companies are best handled by HubSpot's native duplicate manager or a dedicated hygiene tool. AI agents reduce future duplicates by associating extracted stakeholders with existing records rather than creating new ones, but their primary hygiene value is filling deal-level properties, not merging records.
They serve different steps. Breeze suggests record updates after a call and waits for rep approval. AI agents like Sybill write validated values directly to properties with no review queue. Many teams use both: Breeze for content and general assistance, an agent for conversation-to-CRM write-back.
Track fill rates on the deal properties your forecast depends on. Monthly, pull deals in your last two open stages and calculate the percentage with real values in fields like Economic Buyer, Decision Date, and Next Step. Rising fill rates with stable accuracy on spot checks means the automation is working. A drop usually signals an unannounced schema change.
It should be treated like any integration with write access: scoped permissions limited to the properties it needs, a full audit trail of changes, the ability to reverse a write, and a named owner on your side. Vendors that offer SOC 2 Type II compliance and property-level permission scoping meet the baseline. Ask how unmapped values and failed writes are surfaced.
HubSpot data hygiene is the ongoing practice of keeping records complete, accurate, consistently formatted, and free of duplicates so that workflows, reports, and forecasts built on them are trustworthy. It covers contacts, companies, and deals, though most native tooling focuses on the first two.
HubSpot's data quality tools cover duplicate management for contacts and companies, formatting issue detection with automatic fixes on Data Hub Professional and Enterprise, enrichment coverage, and property insights showing empty or unused properties. Conditional stage properties add required fields at deal stage transitions. None of these fill deal qualification data from calls.
AI agents capture the sales call, extract structured values such as stakeholders, budget, timeline, and competitors, map each to a specific HubSpot property by internal value, validate the value against the property's type and options, and write it through HubSpot's API when the call ends. Unmapped values are flagged for review rather than dropped.